
Ian Buck, NVIDIA's vice president of hyperscale and high-performance computing, told 8,000 people at the September 15 AI Infra Summit that AI factories should be measured by tokens per megawatt S¹. The summit more than doubled from 3,500 attendees last year S¹. The reframe challenges the industry's default benchmark of raw throughput, replacing it with a metric NVIDIA can tune through its own software stack: Vera Rubin systems, Dynamo inference software, NeMo libraries and NVIDIA networking S¹.
NVIDIA wants a vendor-tunable metric to replace peak performance
This is the first time NVIDIA has explicitly argued that tokens per megawatt should replace peak performance as the industry yardstick. The 1.4x figure has not been independently verified — no error bars were published, no DSX code has been released for third-party testing, and the number comes from NVIDIA's own communications. The binding constraint on AI factories is power, not silicon. The open question is whether a vendor-owned metric becomes the industry standard, or whether an independent body defines it.
DSX claims 1.4x, but no independent audit exists
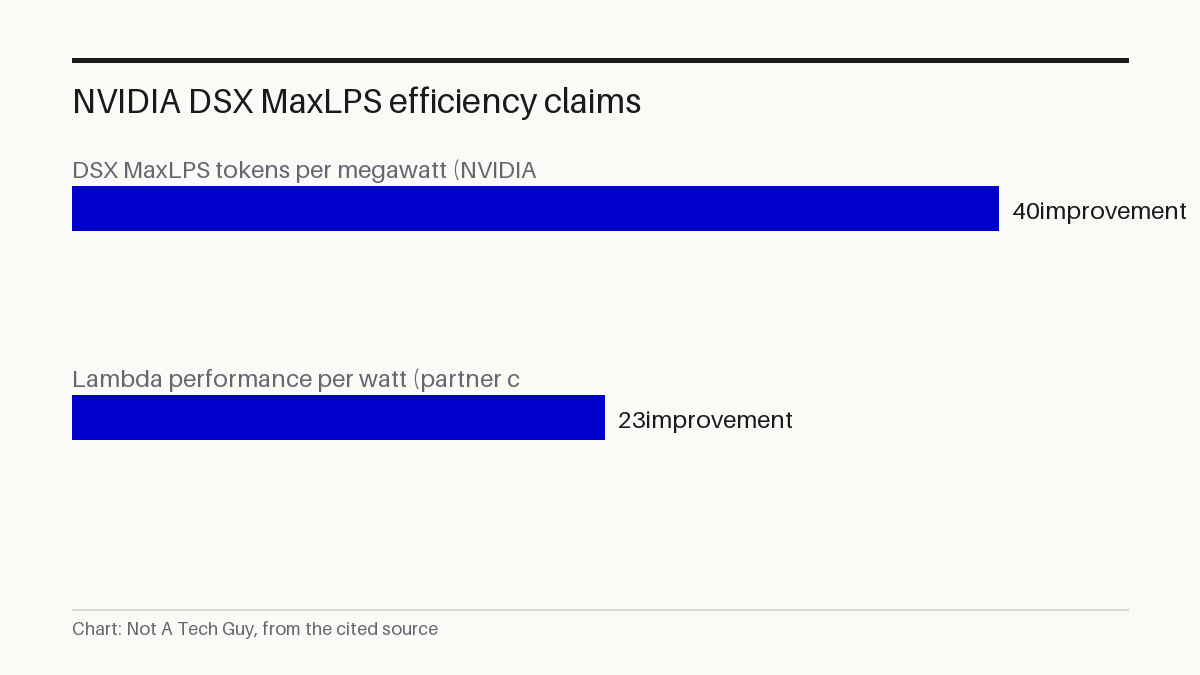
NVIDIA's DSX MaxLPS software can deliver up to 1.4x more tokens per megawatt through factory-wide power optimisation S¹. A technical blog published August 21 by NVIDIA's Sarah McKenney and Harry Petty describes the mechanism: dynamic power allocation and 45-degree thermal site design to maximise throughput within fixed power budgets P⁴.
Lambda, the GPU cloud provider, reported a 23% improvement in performance per watt using DSX MaxLPS S¹. Neither the 1.4x nor the 23% figure has been independently audited — both come from NVIDIA and a partner with a commercial interest in the platform, and no methodology or raw data has been released for outside review.
AI factories can now throttle power on utility signals
The more striking claim came from a demonstration with Silicon Valley Power. Emerald AI and NVIDIA showed an AI factory automatically reducing its power draw in response to hundreds of demand signals from the utility, while protecting AI workload performance S¹. NVIDIA's companion blog, published the same day, describes Silicon Valley Power sending a signal to an AI factory on a hot August evening as air conditioning loads spiked, with Varun Sivaram watching on Zoom P².
DSX Flex, the software handling this, takes in load-shedding requests, demand-response events and pricing signals, then adjusts operations according to a preset workload hierarchy S¹. Emerald AI plans to use DSX Flex for its Conductor grid-responsive power management software S¹. This is a demonstration, not permanent commercial operation.
Amazon, d-Matrix and Pinterest adopt pieces of the stack
Amazon's Annapurna Labs is working with NVIDIA on NVHBM, a custom high-bandwidth memory technology S¹. d-Matrix is integrating NVIDIA's NVLink Fusion platform with its Raptor XPUs, though the source cites integration work, not shipping products S¹. Pinterest is using the NVIDIA Blackwell platform and Dynamo inference software to bring conversational AI to visual discovery, though no public product has launched S¹.
The breadth matters because NVIDIA is selling a system, not a chip. The tokens-per-megawatt metric makes the software, the networking and the power management part of the product, alongside the GPU.
For a data centre operator running inference workloads on NVIDIA hardware, DSX Flex could sit alongside their existing workload scheduler, automatically reducing power draw when their utility sends a demand-response signal and prioritising workloads by a preset hierarchy S¹. NVIDIA's DSX MaxLPS technical blog P⁴ is the most detailed public description of how the optimisation works. The next checkpoint is whether MLPerf or a similar independent body adopts a power-normalised token metric, which would let operators compare NVIDIA's claims against competitors on equal terms.
Sources: S1 — AI Infra Summit: NVIDIA Vera Rubin and DSX Platform Advancements Showc · P2 — From Megawatts to Tokens: How NVIDIA Maximizes AI Factory Production · P3 — [2608.20532] Learning Exact NVIDIA SASS Encoders with $\mathbb{F}_2$ L · P4 — Maximizing AI Factory Performance per Watt with NVIDIA DSX MaxLPS | NV · P5 — NVIDIA DSX OS Delivers Open, Modular Software for Operating AI Factori
Written from 5 sourced items, 5 of them primary.