Machine-learning researchers posted a preprint to arXiv on October 2, 2026, that maps how multimodal large language models fuse visual and textual data across their internal layers S¹. The models perform well on vision-language tasks, but how image and text combine inside them has remained poorly understood S¹. The preprint reports that two dominant architectures take fundamentally different routes to that combination S¹.
My read: This is the first mechanistic comparison I have seen that explicitly contrasts concatenation and native multimodal designs through the lens of fusion pathways. I am skeptical of how generalisable the text-first, vision-later claim for concatenation models is until the specific models tested are named and the experimental conditions are scrutinised. The paper is a preprint with no peer review and no independent replication, so every finding is an author claim. What I would watch is whether the causal intervention experiments, which the authors use to validate their interpretation, hold up under different model sizes and training regimes.
Two architectures, two schedules
The authors examine models from two architectural designs: concatenation architectures, which stitch visual features onto a text backbone, and native multimodal architectures, which are built from the ground up to process multiple modalities together S¹.
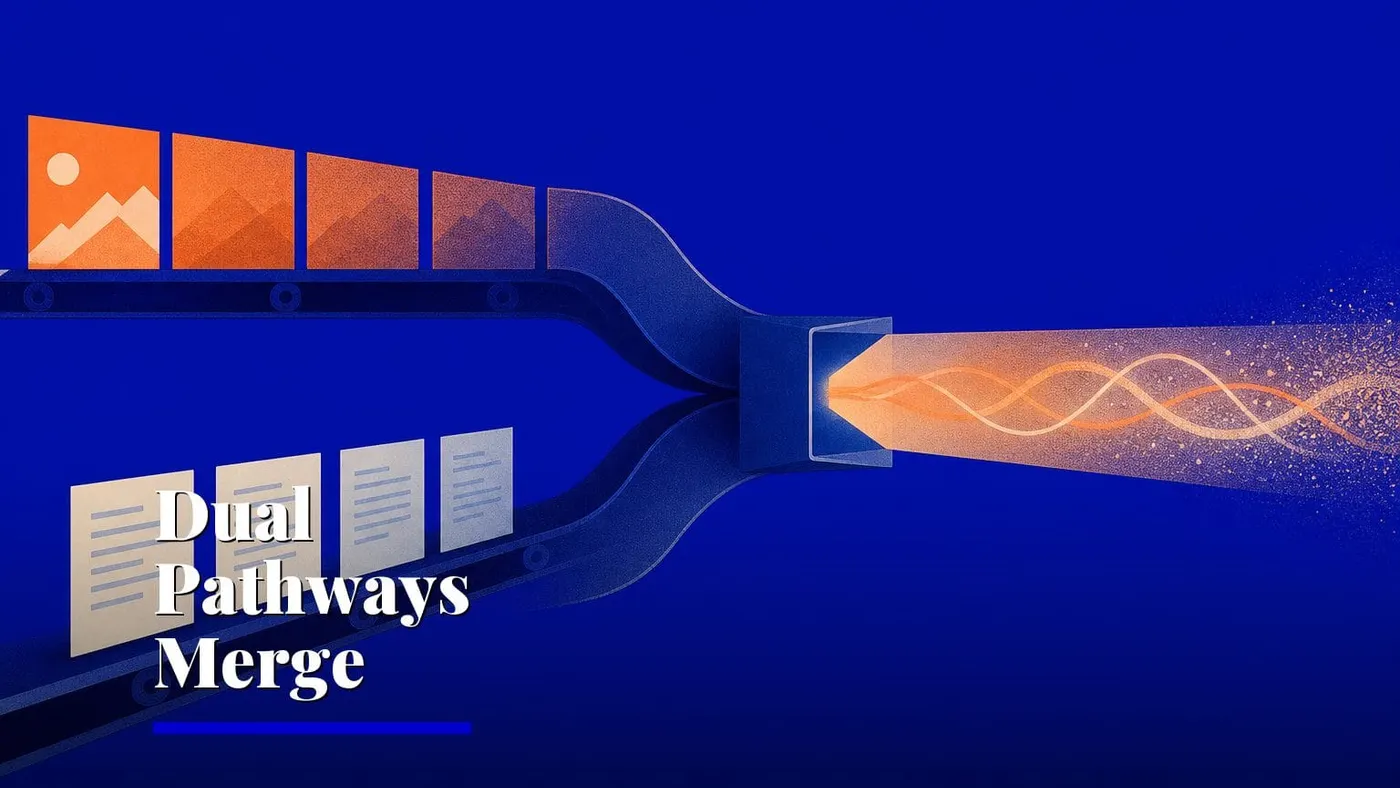
Their central finding is that these two families fuse information on different timelines. Concatenation models follow what the authors call a text-first, vision-later pathway, processing language in early layers and integrating visual information only deeper into the network S¹. Native multimodal models show earlier visual-textual co-adaptation and a reorganisation of the feature space sooner in the processing pipeline S¹.
The distinction matters because it suggests that architecture, rather than training data or scale, determines when and how a model combines what it sees with what it reads. A related June 2026 preprint from Siyuan Liu and Jinyang Wu at Peking University and Tsinghua University reached a compatible conclusion from the opposite direction, arguing that late-layer fusion alone can be sufficient for multimodal models under visual saturation P⁴. Their dual-path routing method pushes vision tokens to later layers, an approach that implicitly treats late layers as sufficient for fusion P⁴.
How they traced the fusion
The authors deploy a toolkit of four techniques to peer inside the models. Alignment decoupling identifies which modality is changing at each layer S¹. Attention routing and entropy measurements characterise how cross-modal information is distributed through the network S¹. Intrinsic dimensionality analysis examines how fusion reshapes the geometry of the feature space S¹. As a supplementary step, the authors use visual CKA, a similarity metric between neural representations, to examine the Platonic Representation Hypothesis, which posits that different models converge toward similar internal representations S¹. This analysis is secondary to the main findings and appears only in passing.
The authors then run causal intervention experiments to validate their interpretation S¹. These experiments test whether the fusion pathways they identified are causally responsible for the model's behaviour, rather than correlated with it. The paper does not report whether these interventions were conducted across multiple model sizes or training configurations.
What would need to hold
Every finding in this preprint is an author claim. The paper has not been peer-reviewed, and no independent group has replicated the two-pathway result S¹. The technical claims about fusion pathways and intrinsic dimensionality are abstract-level observations that may depend on specific experimental conditions not fully detailed in the abstract. The risk is that the text-first, vision-later pattern for concatenation models could be an artefact of the particular models chosen rather than a universal property of the architecture class.
The broader field is actively circling these questions. A GitHub repository for cross-architecture merging of large language models, created in February 2026, has drawn six stars P³. The OpenMMReasoner project from EvolvingLMMs-Lab, accepted at CVPR 2026, has 164 stars on GitHub and focuses on multimodal reasoning P⁵. Both signal that researchers are working on the same problem from different angles: how to make multimodal models reason more effectively, which requires understanding what happens inside them.
A team building a multimodal model for medical imaging, where a wrong fusion pathway could mean the model ignores a visual anomaly in favour of a text cue from the patient record, would use this diagnostic framework to check whether their architecture routes visual information early enough.
The paper's toolkit gives such a team a way to inspect their model's internal behaviour before deployment.
The authors state their work provides a mechanistic perspective for understanding multimodal fusion and supports architecture-aware diagnostics of multimodal representations S¹. Whether that framework survives peer review and independent testing is the next checkpoint. The preprint is available on arXiv now S¹.
Sources: S1 — Architecture-Dependent Fusion Pathways in MLLMs · P2 — Late-Layer Fusion is Enough: Dual-Path Vision Token Routing for Multim · P3 — chenhangcuisg-code/Cross-Architecture-Merging-for-Large-Language-Model · P4 — [2606.09131] Late-Layer Fusion is Enough: Dual-Path Vision Token Routi · P5 — EvolvingLMMs-Lab/OpenMMReasoner
Written from 5 sourced items, 4 of them primary.