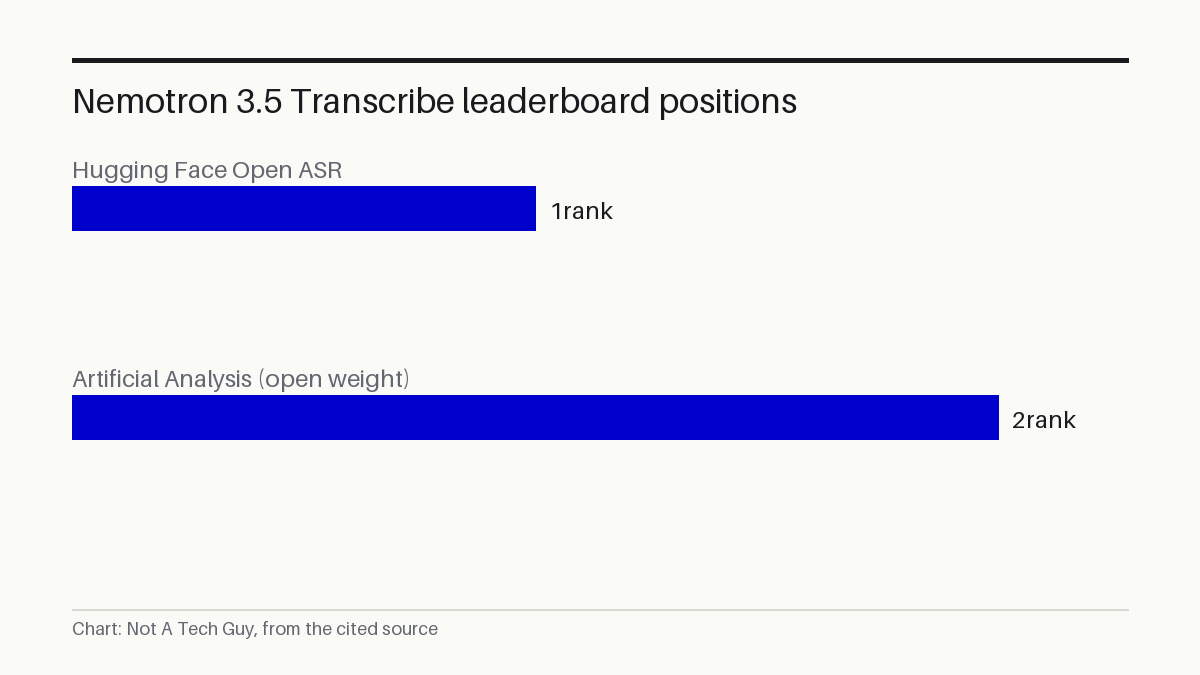

NVIDIA updated its RTX Spark laptop line on October 28, introducing a speech-to-text model with 4.3 billion parameters that the company says tops the Hugging Face Open ASR leaderboard S¹. That ranking has not been independently confirmed; on a separate leaderboard, Artificial Analysis, the same model places second among open-weight systems, and NVIDIA's comparison framing lacks outside verification S¹.
My read: This is the first time I've seen NVIDIA push a speech-to-text model as a flagship laptop feature rather than a data-center product. The 80% fewer parameters claim is striking, but it's NVIDIA comparing its model against an unnamed rival on a leaderboard it doesn't control, so I'd wait for independent benchmarks before calling it settled. The agent GPU management controls in the NVIDIA App are the quieter, more consequential detail. If background agents can actually share a laptop GPU without starving your foreground work, that changes the pitch for "AI PC" from marketing to something a developer could build on.
The RTX Spark laptops went on sale October 16 from six manufacturers: ASUS, Dell, HP, Lenovo, Microsoft and MSI S¹P⁴. The hardware configuration combines a Blackwell RTX GPU and a Grace CPU in one superchip package, offering as much as 128GB of unified memory and peak FP4 AI throughput reaching 1 petaflop S¹. Nobody outside NVIDIA has verified the petaflop figure, which is a vendor peak-performance claim, not a measured workload result.
Nemotron 3.5 Transcribe fits 4.3B parameters into a laptop footprint
Nemotron 3.5 Transcribe covers four capabilities — turning speech into text, identifying who is speaking, translating between languages, and responding to questions about recorded audio, all controllable through natural-language instructions S¹. A developer could prompt it to format medical dictation using specific product names, or to tag speakers in a multi-person interview by role rather than by generic labels like "Speaker 1" S¹.
The model transcribes 40 languages, including seven Indic languages S¹. Its weights are open and available on Hugging Face today, which means developers can run it on their own hardware rather than sending audio to a cloud API S¹. That matters for any workflow governed by privacy rules, from clinical notes to legal depositions.
NVIDIA says the model's 4.3 billion active parameters are roughly 80% fewer than the number-one open-weight model on Artificial Analysis S¹. The comparison relies on NVIDIA's own framing, and the evidence pack includes no independent benchmark data to confirm it. What is verifiable: the model is downloadable now, and quantized versions for local deployment on RTX Spark and DGX Spark systems, Jetson AGX Thor devices, and Blackwell data center GPUs are listed as "coming soon" without firm dates S¹. NVFP4 versions will be deployable through NeMo-Speech.cpp or vLLM S¹.
NVIDIA App adds GPU priority toggles for foreground and background workloads
New settings in the NVIDIA App will give users a toggle to allocate GPU priority between whatever they are actively using and any AI agent running behind the scenes S¹. A user could keep a game running smoothly while a transcription agent processes a meeting recording in the background, or flip the priority to give the agent more compute if the game is paused S¹. For a developer who keeps a coding agent running alongside their IDE, the toggle means they can cap how much GPU compute that agent draws without manually suspending it each time they switch to a foreground task S¹.
The feature requires hardware-accelerated GPU scheduling to be enabled in Windows S¹. NVIDIA has not said when the controls will roll out beyond listing them as part of the current update.
LFM3, a family of open models, will have day-zero support on RTX Spark S¹.
DLSS and ray tracing titles expand the RTX Spark catalog
Phantom Blade Zero will launch with ray tracing and NVIDIA DLSS 4.5 support S¹. Minecraft with path tracing and DLSS via RTX Remix 1.6 is available now for RTX Spark S¹. Neither feature is exclusive to RTX Spark hardware.
NVIDIA's own developer page for RTX Spark P⁵ frames the platform around local model execution for privacy and cost control, positioning these laptops as workstations for developers who want to run AI without cloud token costs.
The quantized Nemotron 3.5 Transcribe builds for RTX Spark remain the key pending item. NVIDIA has not given a release date.
Sources: S1 — Thin, Light and Built for Everything: NVIDIA RTX Spark Windows Laptops · P2 — All Systems Go: Global PC App Ecosystem Ready for NVIDIA RTX Spark | N · P3 — gittensor-ai-lab/sparkinfer-runtime · P4 — NVIDIA RTX Spark PCs Available Today — A New Beginning for Windows PCs · P5 — Run LLMs on Your NVIDIA Device | RTX Spark
Written from 5 sourced items, 5 of them primary.