
Technology & AI
Vulnerability scanner divergence explained in new arXiv framework
arXiv paper explains why vulnerability scanners give different results for the same software, tracing inconsistency to a distributed ecosystem.
The AI knowledge 99.9% of people never discover
Daily AI and technology coverage — models, chips, agents and research, and what each development actually means for you and your business.
552 stories
arXiv paper explains why vulnerability scanners give different results for the same software, tracing inconsistency to a distributed ecosystem.
A new arXiv preprint shows LLMs can read threat reports, generate attack playbooks, and self-correct failures, reaching 84% with Claude Sonnet 4.5.

An arXiv preprint shows an RL agent using a Lyapunov exponent reward found the Kapitza pendulum and a new upright state, with implications for robotics.

Structural priors lift LLM vulnerability recall from 20% to 100% on synthetic benchmarks, but real CVE data exposes a 51-point collapse.

A replay analysis of three LLM agent benchmarks finds the safe partial-run fraction ranges from 15% to over 95%, with no universal shortcut.
A 17 July arXiv preprint shows attackers can weaponise setup docs to trick AI coding agents into installing untrusted dependencies across npm and Cargo.

An arXiv preprint introduces AutoSynthesis, a multi-agent system that turns a clear research question into a full meta-analysis report.

A new arXiv preprint proposes mutable sketches that update user embeddings on-the-fly, cutting data reads to 1.8% and eliminating retrain cycles.
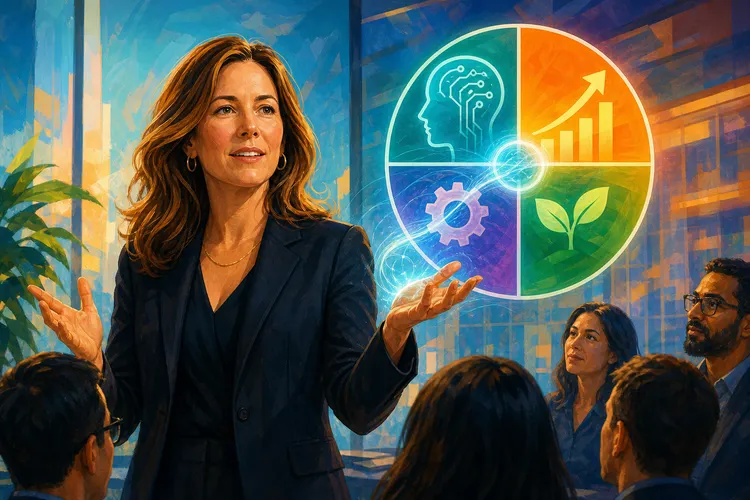
Sarah Friar's framework shifts AI measurement from model benchmarks to useful work, cost per task, dependability and return on compute.

MemPoison benchmark tests 1,227 attacks across 10 model families, finding write-time defenses miss sophisticated memory corruption in LLM agents.

ReBound, a new arXiv preprint, reuses cached query results to answer follow-up questions at reduced or zero additional privacy cost for analysts.
A July 2026 arXiv preprint reframes security testing for AI systems, arguing attackers can violate operational objectives without breaching infrastructure.