
Technology & AI
Best AI agents fail 50% of visual tool tasks, Apple benchmark shows
A new open benchmark with 500+ tools reveals even frontier AI models can't reliably read an image and act on it, with most failures traced to seeing, not
The AI knowledge 99.9% of people never discover
AI agents explained — autonomous assistants, coding agents and the research on where they work and where they fail.
117 stories
A new open benchmark with 500+ tools reveals even frontier AI models can't reliably read an image and act on it, with most failures traced to seeing, not
A new Lean 4 library formalises three quantum coding theorems and builds reusable infrastructure for AI-assisted proof search in quantum information
Malaika, a multi-agent AI framework posted to arXiv this month, uses three grounding mechanisms to make malware analysis more precise and auditable.
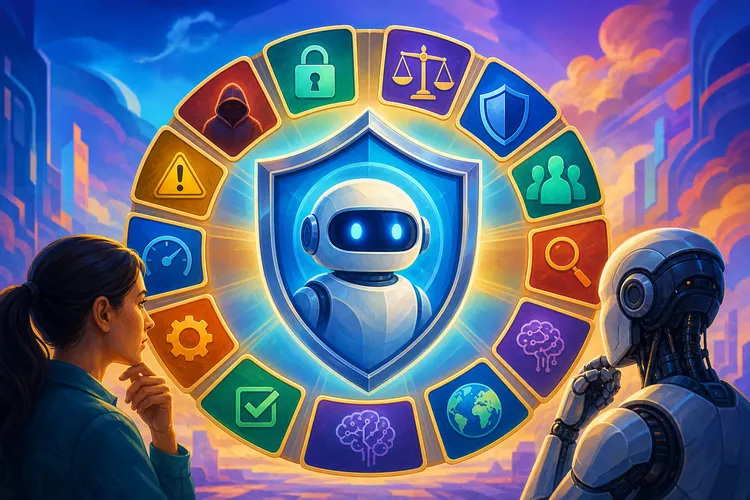
TrustX ARC, a new arXiv preprint, scores agentic AI risk across 12 dimensions into three governance tiers for risk officers, developers and regulators.
A new arXiv preprint pairs an LLM planner with a forecasting model to guard industrial control systems, recording zero hallucinated actions in attack
KV-PRM reads the memory AI models already produce during generation, slashing the cost of verifying multi-agent reasoning chains by up to 5,000x.
A new arXiv paper proposes the Hypothesis Evolution Protocol, making AI agents' scientific reasoning explicit and auditable instead of buried in logs.
A new arXiv survey maps how LLMs could move front-end chip design from isolated tasks to autonomous agents, but offers no benchmarks to prove it works.

LLM-as-a-Verifier treats checking AI answers as a scaling axis, hitting 86.5% on Terminal-Bench V2 and 78.2% on SWE-Bench Verified without extra training.