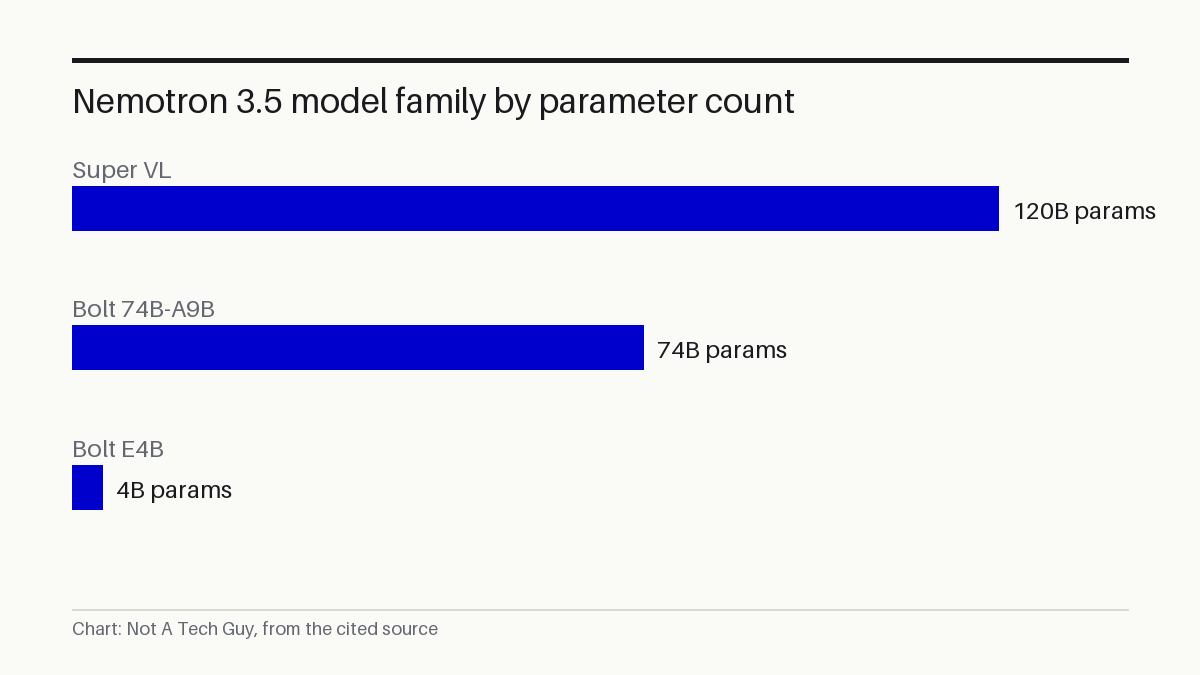
NVIDIA released an open 120-billion-parameter model today that it says matches its largest reasoning model's accuracy on multimodal agentic tasks at roughly one-fifth the parameter count S¹. The company claims the model, Nemotron 3.5 Super VL, is five times faster than the next best open agentic model in its class S¹. Both figures are the vendor's own: NVIDIA provides no error bars, has released no benchmark code for independent reproduction, and names no comparator model for the speed claim.
My read: This is the first time I've seen NVIDIA push a model that explicitly targets the gap between data-centre reasoning engines and desktop-class hardware in a single family. I don't buy the "5x faster" claim yet, because NVIDIA names no comparator model and the benchmark is unspecified. What I find more credible is the architecture: NVIDIA's NeMo documentation confirms a hybrid Mamba-2 plus Attention mixture-of-experts backbone, a design that spreads computation across specialised sub-networks, paired with a RADIO v2.5-H vision encoder P⁶. That is a genuine efficiency play rather than a brute-force scale-up. The real test will be whether organisations post-training on their own data can match the accuracy NVIDIA reports on its own benchmarks.
Alongside Super VL, NVIDIA shipped two edge models designed to run on consumer and workstation hardware rather than data-centre clusters S¹. Nemotron 3.5 Bolt 74B-A9B 24GB uses native 2-bit quantization, a compression technique that reduces each model weight to two bits of precision, to fit a 74-billion-parameter model into 24 gigabytes of memory S¹P⁴. That is the memory capacity of a single RTX 4090, meaning a model with 74 billion parameters can run alongside other desktop applications on a consumer GPU. For a solo developer with a desktop RTX 4090, the 24 GB footprint means a 74-billion-parameter agent runs locally alongside other desktop applications rather than requiring a data-centre GPU S¹.
NVIDIA ranks the Bolt 74B-A9B as the number one open model in its class on PinchBench and number two on BrowseComp, a web-browsing agent benchmark S¹. These rankings are NVIDIA's own; no third party has reproduced them, no error bars are published, and the underlying benchmark code has not been released.
The third model, Nemotron 3.5 Bolt E4B 4GB, targets physical and conversational agents on GeForce RTX, Jetson, and RTX/DGX Spark hardware S¹. It is designed for a 4-gigabyte memory footprint, small enough for embedded devices. NVIDIA says it will be available on October 23 S¹.
Post-training adoption spans finance, cybersecurity, and coding
Dozens of organisations are post-training Super VL on their own data, according to NVIDIA S¹. Scale AI tailored the model for two separate deployments: a vendor credit finance agent at Skydance and a due diligence agent at EY for mergers and acquisitions work S¹. AfterQuery reworked it for Hebbia to parse credit agreements S¹. AI21 and Alice each adapted it for cybersecurity attack-resilience use cases, while Mercor trained against the APEX-SWE coding benchmark to produce agents that can plan, write, and debug code S¹. ModelScope offers fine-tuning through its ms-swift toolkit S¹.
The pattern matters because it addresses a persistent problem with agent reliability: organisations that cannot inspect or fine-tune the model behind their agents have no way to close those gaps. Super VL's open-weight approach lets a firm post-train on proprietary data, deploy on its own infrastructure, and retain oversight of what the model produces S¹. For a mortgage broker building a document-checking agent, that means the model never sends client files to a third-party API.
Nemotron family now spans desktop to data-centre workloads
Super VL and Bolt join a Nemotron family that already includes Lightning, released in August for high-throughput workloads, and Ultra, which handles the hardest reasoning tasks S¹. According to NVIDIA's product page, the lineup targets long-running AI agents with efficient, multimodal, open-weight models P³. The expansion comes as NVIDIA pushes deeper into infrastructure buildout, including 2 GW of AI factory capacity targeted in Australia by 2027.
Super VL and Bolt 74B-A9B are available now S¹. Bolt E4B 4GB lands on October 23 S¹.
Sources: S1 — Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With · S2 — Open From Data Center to Desktop: NVIDIA Expands Nemotron Family With · P3 — Build Agentic AI with Multimodal Foundation Models | NVIDIA Nemotron · P4 — nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB · Hugging Face · P5 — open-index (OpenIndex) · P6 — Nemotron 3.5 Super VL | NVIDIA NeMo AutoModel
Written from 6 sourced items, 5 of them primary.