Technology & AI
AI agent benchmark tests tool-switching when reliability shifts
A new arXiv paper uses cognitive psychology's set-shifting concept to test whether LLM agents adapt when reliable tools silently change mid-session.
The AI knowledge 99.9% of people never discover
AI agents explained — autonomous assistants, coding agents and the research on where they work and where they fail.
117 stories
A new arXiv paper uses cognitive psychology's set-shifting concept to test whether LLM agents adapt when reliable tools silently change mid-session.
A new arXiv preprint introduces an Information Flow Graph monitor that stops AI coding agents secretly weakening security before deployment.
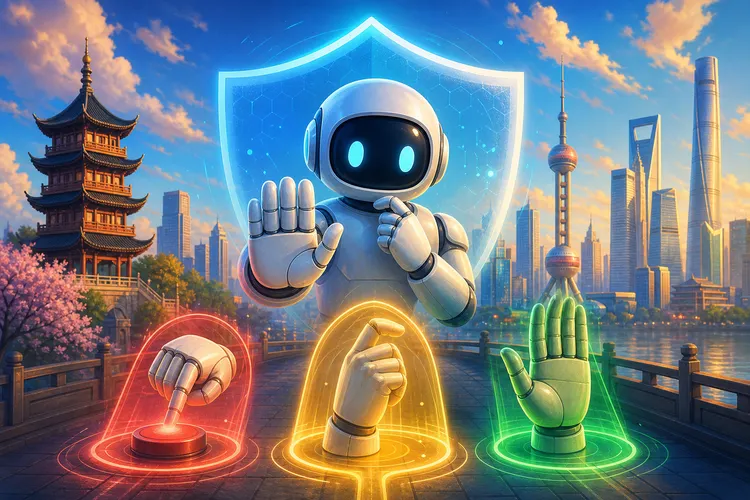
A new arXiv paper from ShanghaiTech replaces binary safe/unsafe guards with a three-way EXECUTE-ASK-REFUSE routing that cuts alert fatigue for anyone
Harness Handbook from Tencent and four universities builds a behaviour-to-code map for agent harnesses that cuts planner tokens and improves edit
New arXiv paper finds automatically evolving agent scaffolding doesn't consistently outperform test-time scaling, with limited generalization to new tasks.

A new preprint tested 327 real-world agent skills and found vulnerabilities across the entire skill lifecycle, from admission to evolution.

An arXiv preprint introduces AutoSynthesis, a multi-agent system that turns a clear research question into a full meta-analysis report.
New STOCKTAKE benchmark: LLM agents detect up to 88% of hidden supply-chain failures but two of four models score below a blind baseline on action.

NVIDIA's Vera Rubin platform reframes AI economics around intelligence per dollar, making continuous post-training the central workload for agentic AI.
A study of 2,361 popular GitHub repos finds most generate just one or two AI-agent pull requests per quarter, with heavy use in small teams.

Oracle agent memory hits 93.8% on LongMemEval with 10.7x fewer tokens than flat-history baselines, per a new arXiv preprint on long-horizon AI agents.
A new arXiv survey formalises how AI agents update their own prompts, memory and tools with minimal human input, and what breaks when they do.