Technology & AI
JAXBench: curated TPU docs lift AI kernel correctness 5.8% to 37%
JAXBench, the first TPU benchmark for AI kernel generation, shows curated docs lift correctness from 5.8% to 37.3% and reach 1.6x speedup over XLA.
The AI knowledge 99.9% of people never discover
AI model releases and benchmarks — what each new model actually changes for the people who use it.
191 stories
JAXBench, the first TPU benchmark for AI kernel generation, shows curated docs lift correctness from 5.8% to 37.3% and reach 1.6x speedup over XLA.
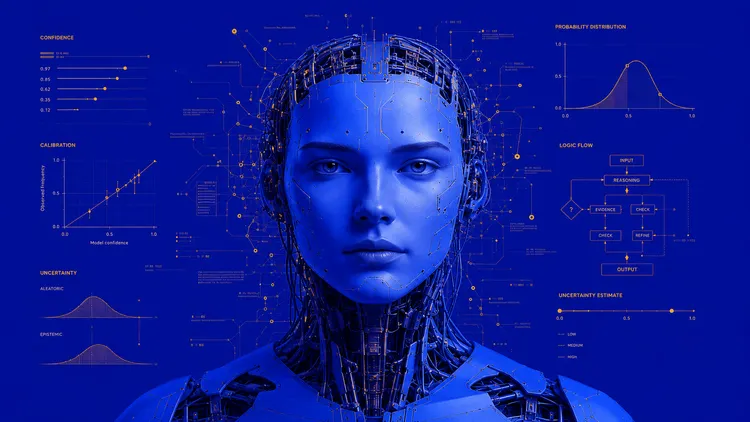
New arXiv paper finds calibration, the standard test for AI confidence, misses deeper incoherence in how models estimate their own certainty.
A new arXiv preprint claims small language models trained on synthetic data outperform prompt-based LLM safety checks for hallucination and topic drift.
New arXiv preprint proposes Probabilistic Concept-Aware Steering, fixing incoherent behaviour in LLM steering vectors for open-weight model teams.
PEARL puts a math solver inside the LLM loop to test, debug and revise optimization models, beating models 170× larger on verified solve rates.
A July 2026 arXiv preprint introduces TPIPS, a text-prompted image similarity metric showing frontier vision-language models lag human perception.
New arXiv framework uses twelve reasoning angles to separate jokes from hate in memes, hitting 80.3% humor and 75.9% hate detection on two benchmarks.
Six LLMs tested across navigation, triage and finance tasks showed stable risk preferences, a hidden trait anyone deploying AI agents needs to understand.
MOSAIC, posted on arXiv on July 21, lifts long-conversation accuracy 27 points and catches 66% of factual conflicts before they corrupt an agent's memory.
New arXiv preprint shows AI agents can be redirected by reordering true facts, with 83.3% success across GPT, Claude, Gemini, DeepSeek and Qwen.
A new arXiv preprint maps 43 operations that corrupt self-hosted AI agents via legitimate OS calls, finding a residual surface no defense can distinguish.
LaCache caches unchanged tokens during diffusion LLM denoising, cutting inference 1.3X standalone and up to 40X stacked with other acceleration methods.